Watch the podcast
Cynthia & Paul from the ExpSoft Labs walk you through ExpSoft Uncensored Captioner 1.1.2.2 — about 5 minutes.
The video plays from YouTube once you press Play. Watch it on YouTube
AI-powered captioning of images and video using abliterated (uncensored) QwenVL models with booru-style tag generation via WD14 SwinV2 Tagger. A single-file test-bench (pre-tag / post-tag / multi-replace, tag-forcing, "only booru tags"), batch folders with drag & drop, and keyframe-based video captioning for AI training datasets. Everything runs locally — no API keys, no cloud, no censorship.
Cynthia & Paul from the ExpSoft Labs walk you through ExpSoft Uncensored Captioner 1.1.2.2 — about 5 minutes.
The video plays from YouTube once you press Play. Watch it on YouTube
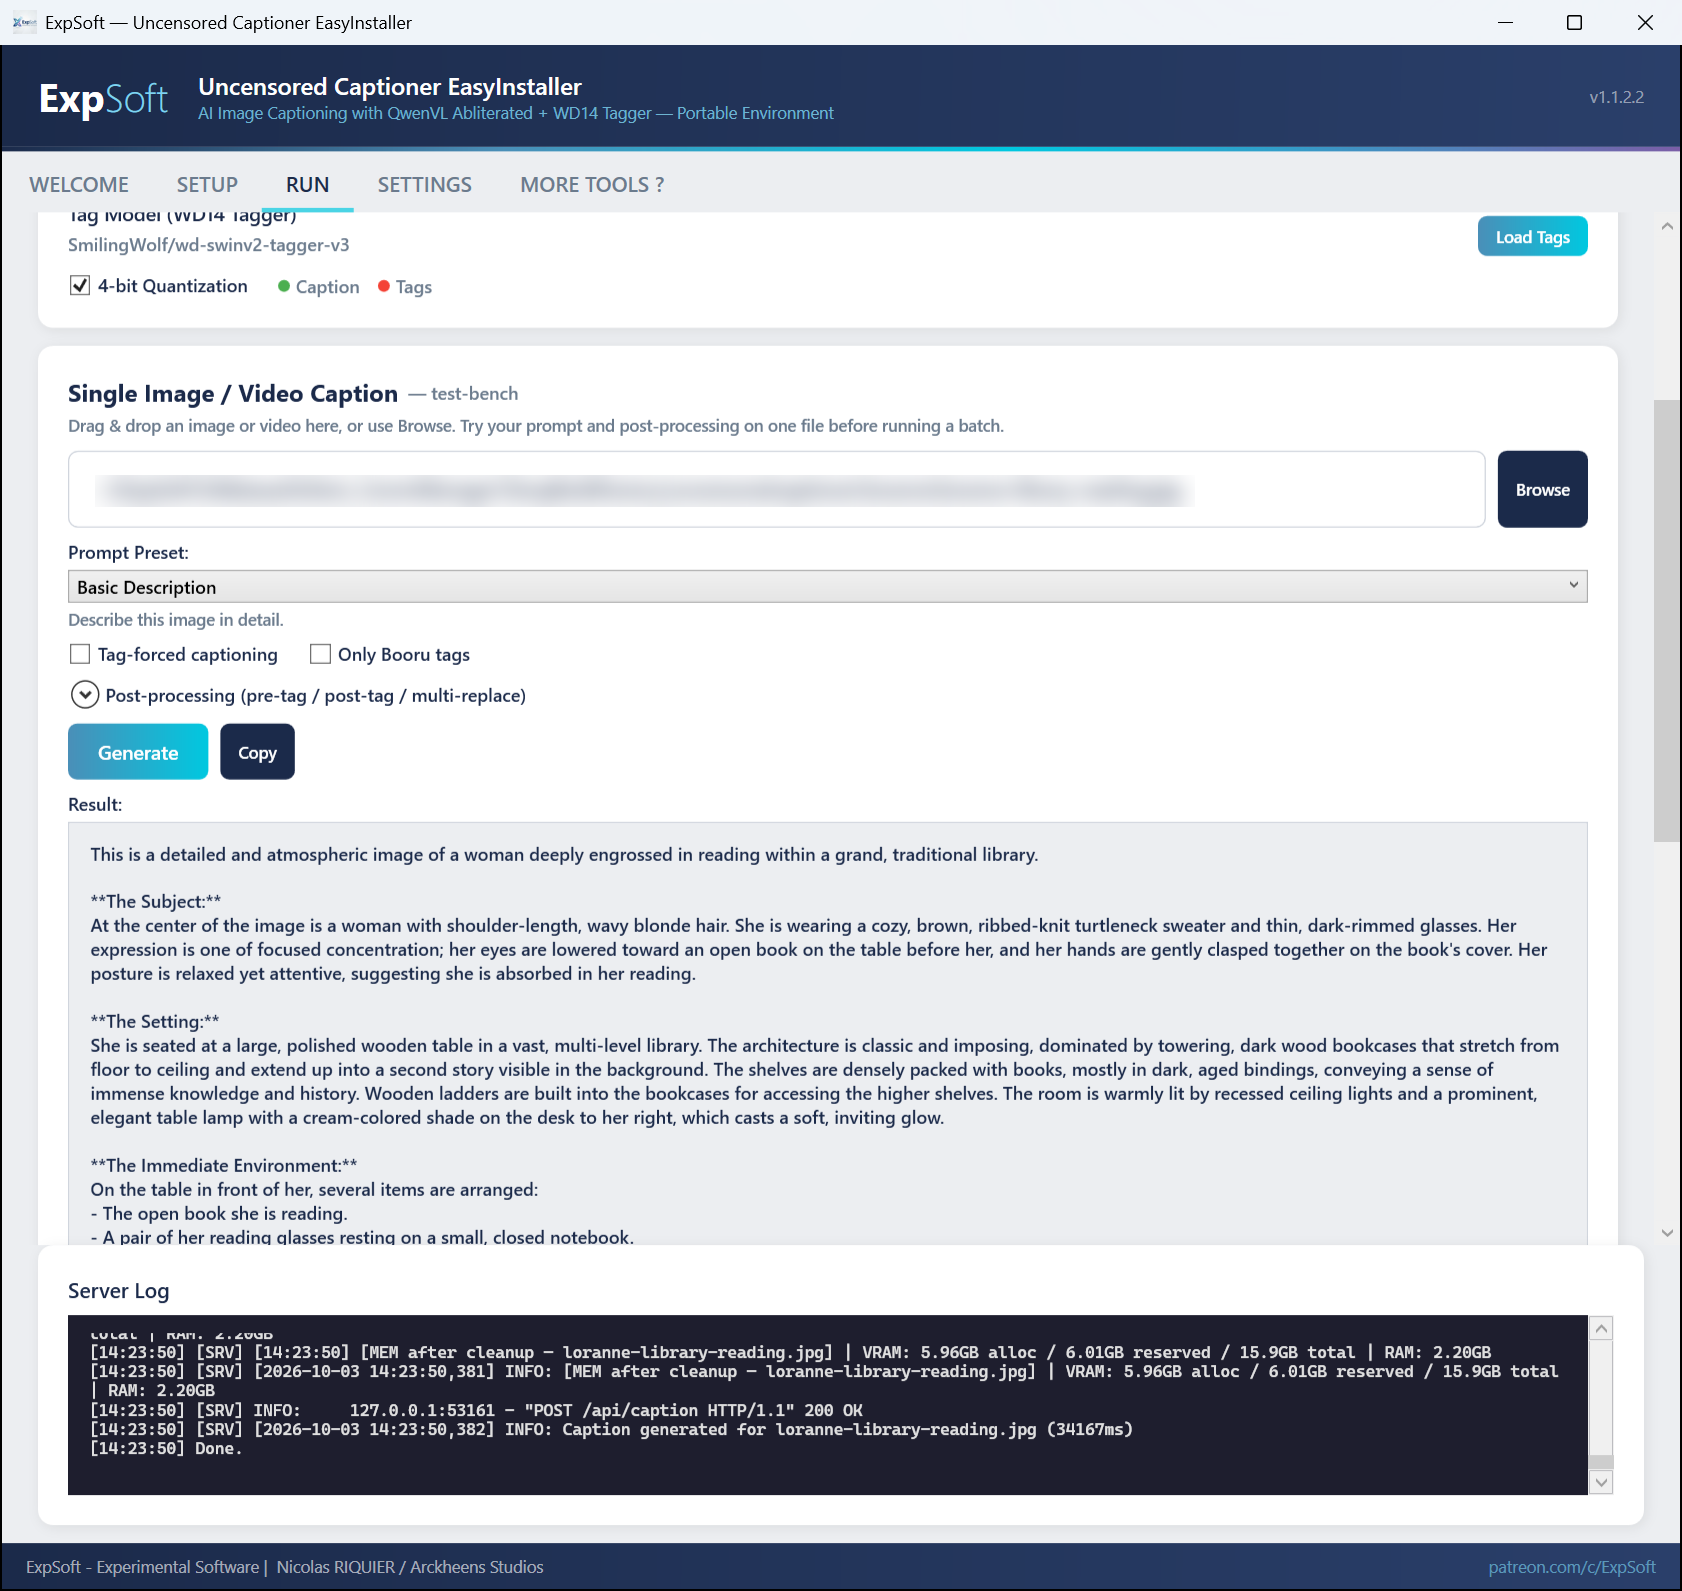
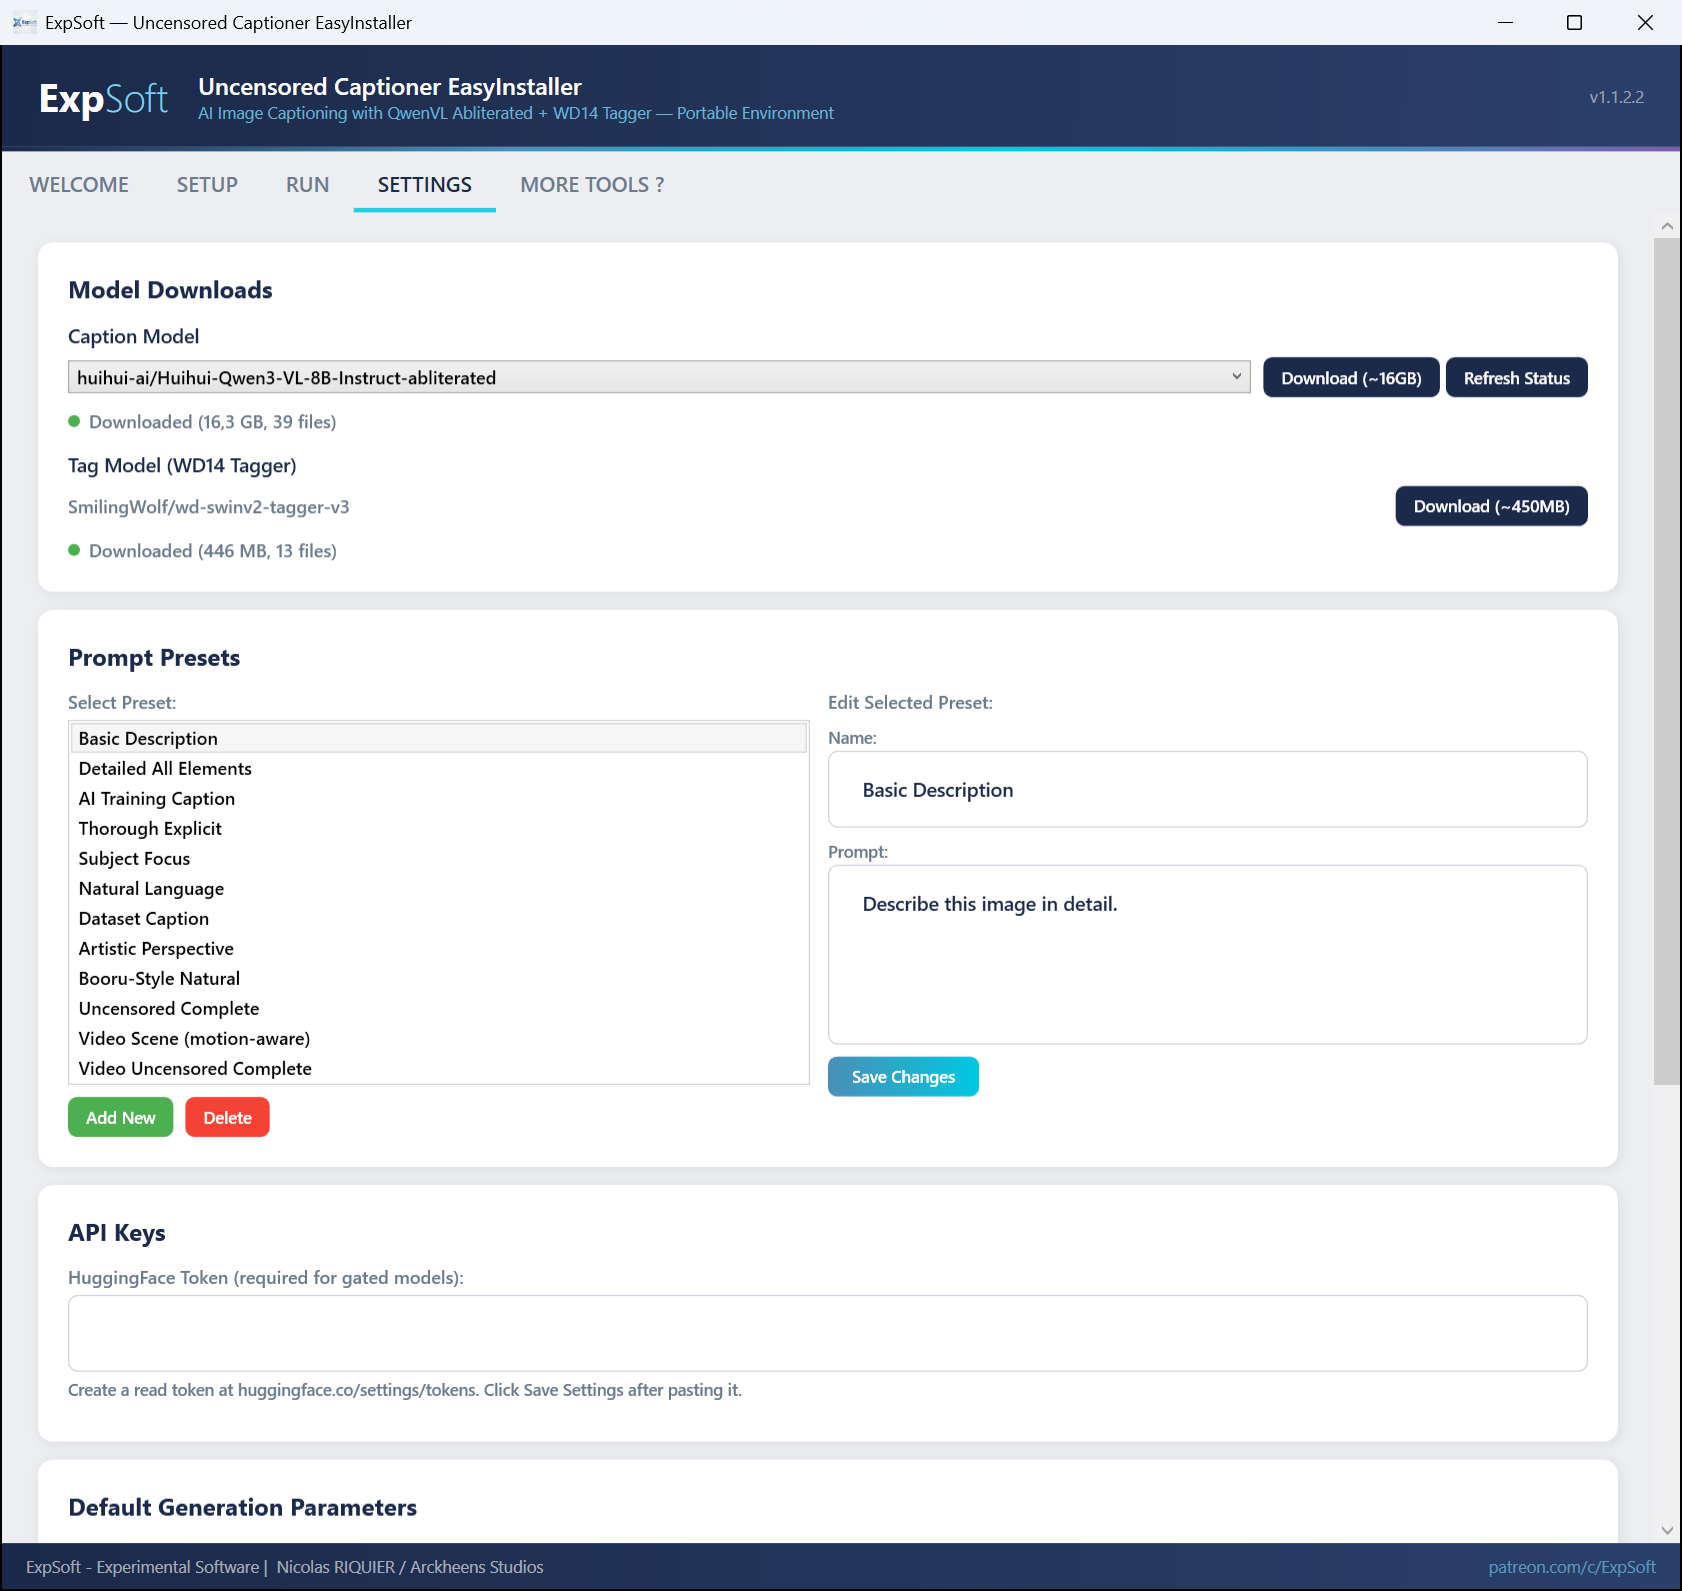
Click any image to zoom. Captured on V1.1.2.2.
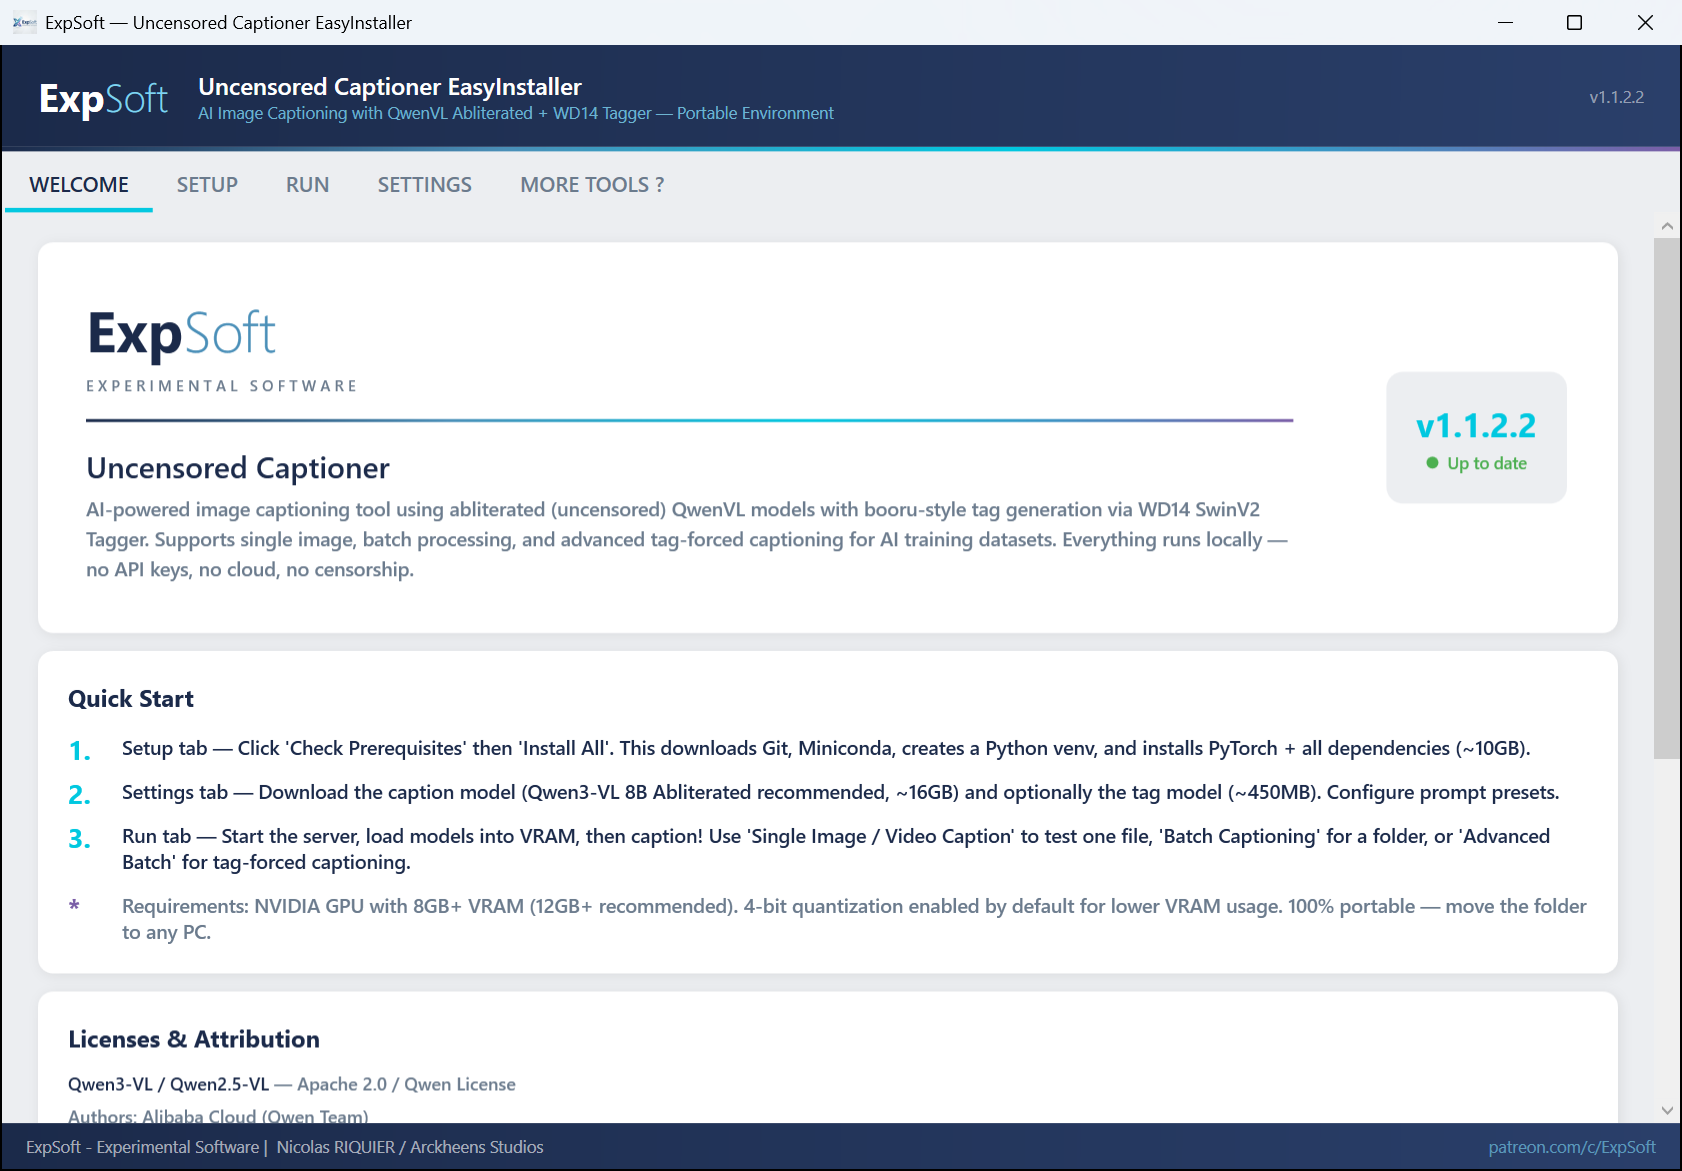
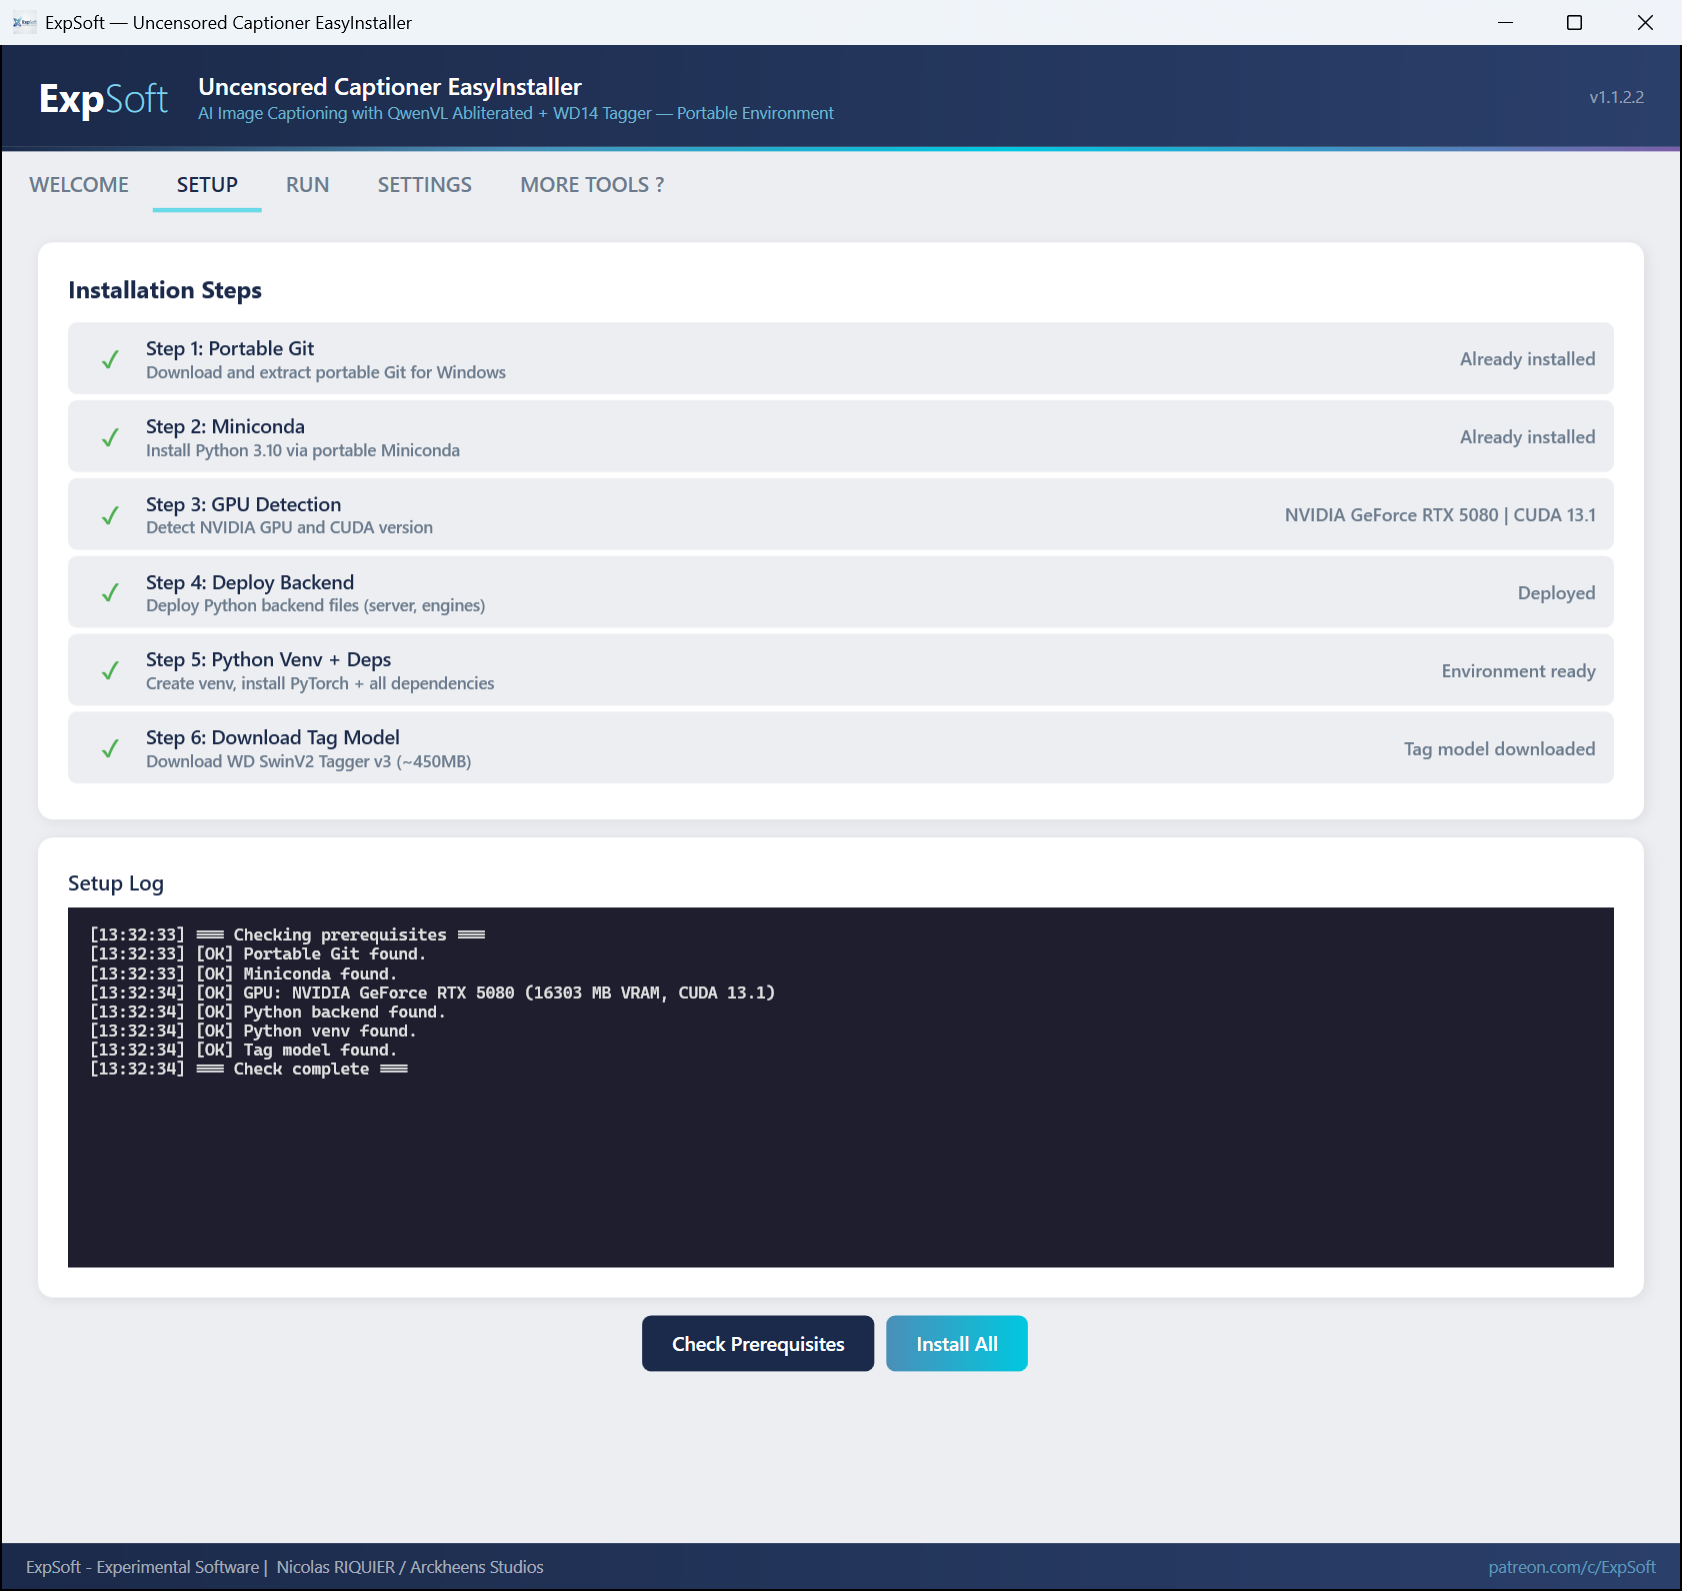
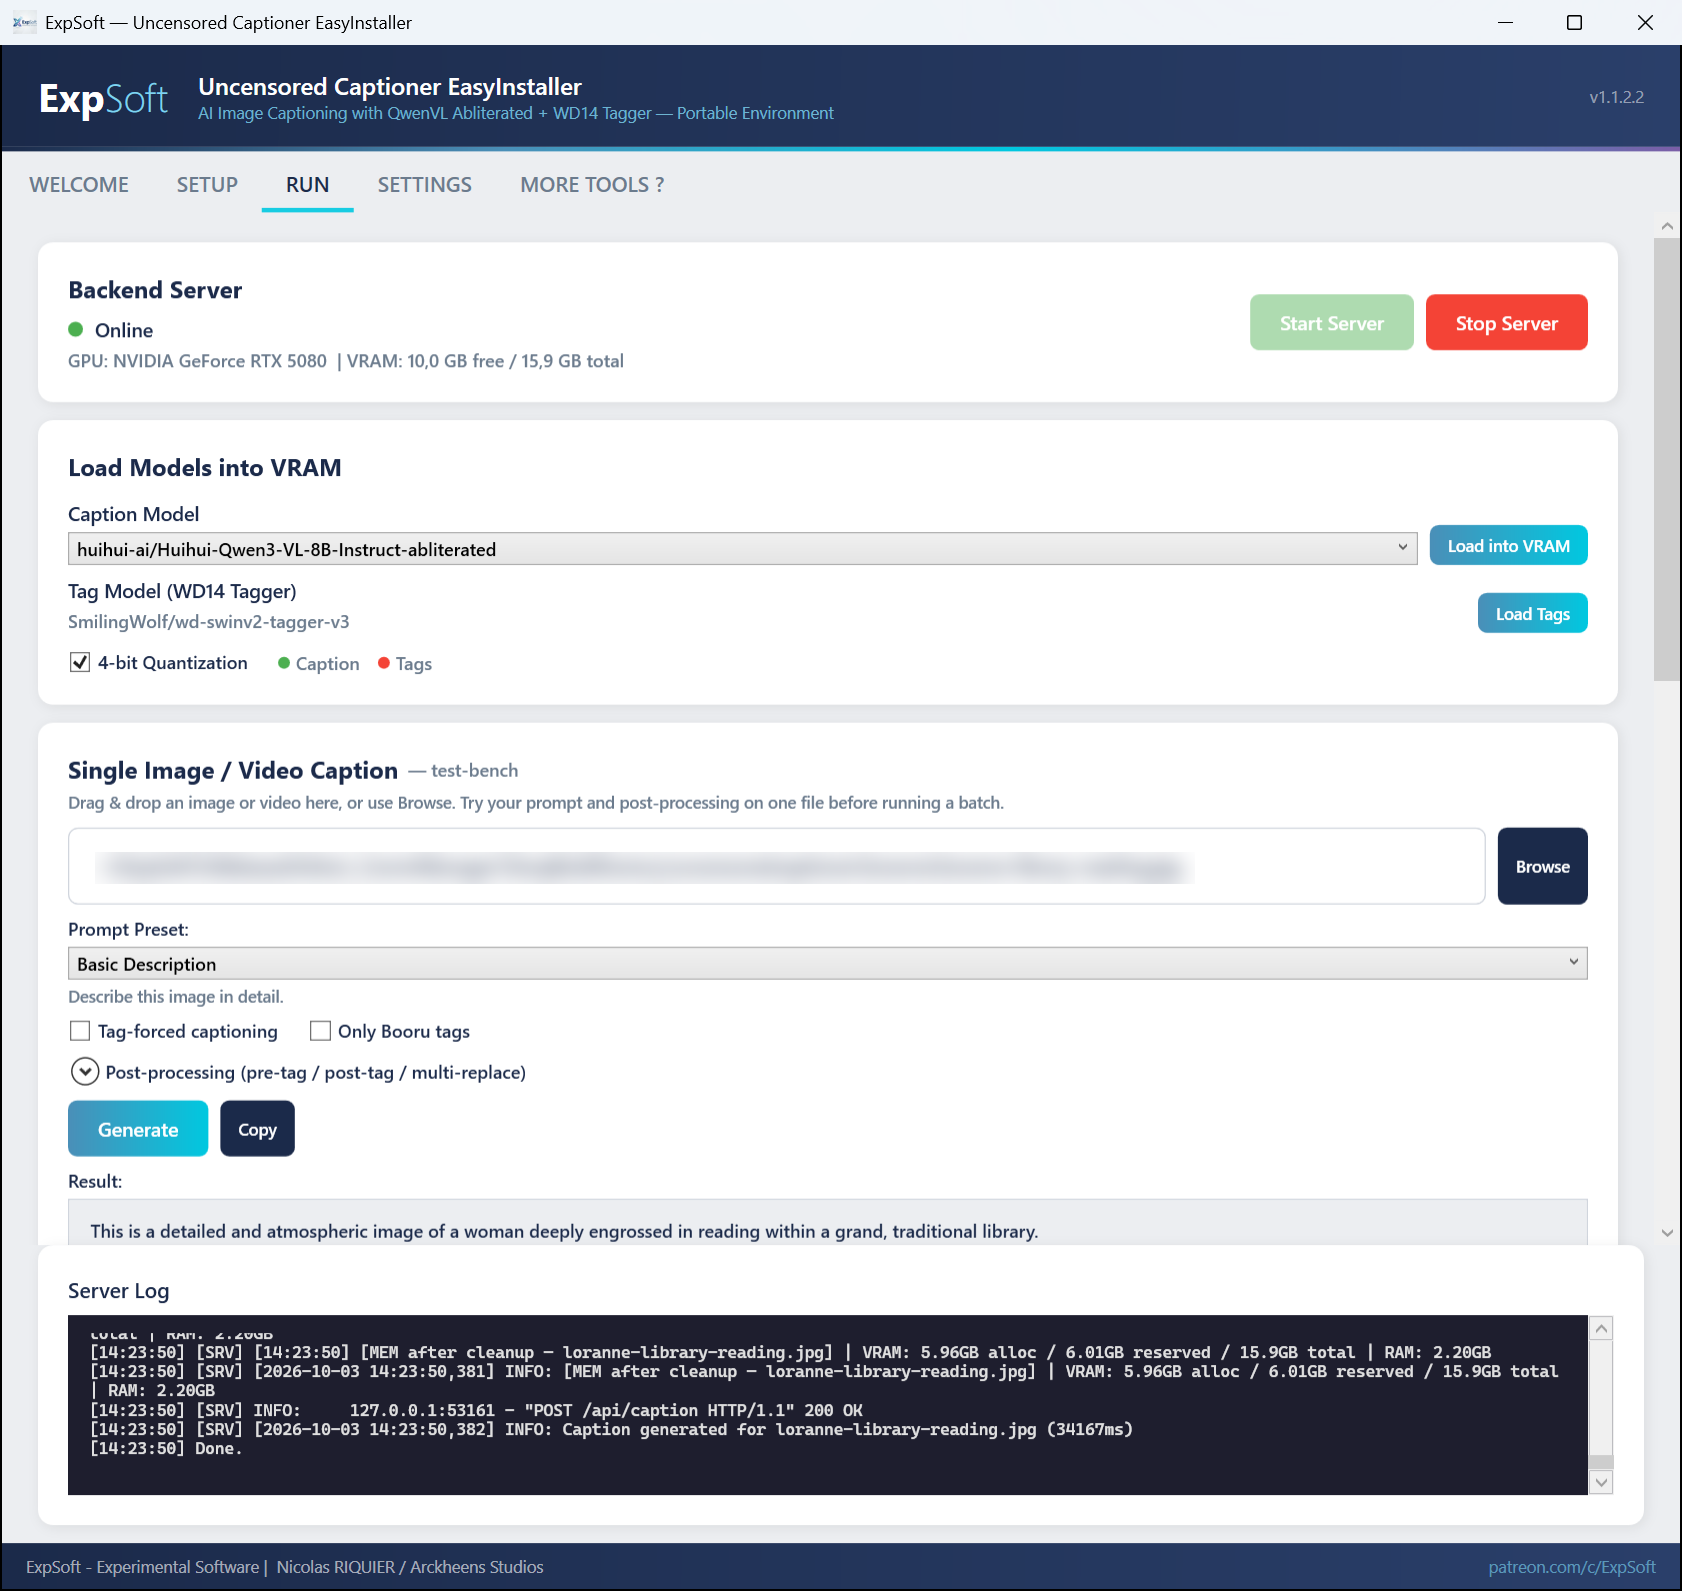
Uncensored AI captioning, fully local, fully portable.
8 pre-configured uncensored caption models — Qwen3-VL 8B Instruct & Caption-it, 4B (low VRAM) and 32B (high-end), plus Qwen2.5-VL 7B abliterated variants. No refusals, no censorship, no omissions.
Booru-style tag generation with WD SwinV2 Tagger v3. Configurable confidence threshold. Character tags, rating tags, and general tags.
12 editable caption prompt presets out of the box (10 for images, 2 for video). From basic descriptions to dataset-focused, artistic, booru-style, and uncensored complete. Add, edit, delete your own.
Drag & drop an image or video, pick a preset, then dial in pre-tag / post-tag / multi-replace, optional tag-forcing, or an "only booru tags" output — before launching a batch. One-click copy of the result.
Drag & drop a folder of images or videos. Batch caption or tag everything with progress tracking. Skip existing .txt files for resumable runs, or output only booru tags.
Point it at a video and get one coherent scene caption: N evenly-spaced keyframes are sampled and read together by the VLM. Uses a portable bundled FFmpeg (imageio-ffmpeg) — no system install. Works in single and batch.
Best for AI training datasets. Tags are detected first with WD14, then injected into the caption prompt via {tags} template. Pre/post tags, multi-replace rules, character & rating tag control.
Download models directly from HuggingFace with progress tracking (speed, size, file count). Uses the new HF xet download system for maximum speed. No API key needed.
See at a glance which models are downloaded, their size on disk, and whether they're loaded into VRAM. Green/red indicators everywhere.
bitsandbytes 4-bit loading divides the video memory by about three: the recommended 8B model uses about 6 GB (measured on our RTX 5080 16 GB). Enabled by default, toggleable per session.
Portable environment. Local Git, Miniconda, Python venv, models, cache — everything relative to the exe. Move the folder to any PC, even change drive letters. Auto-patching on relocation.
Separate builds for RTX 40xx (CUDA 12.4) and RTX 50xx (CUDA 12.8). Each installs the correct PyTorch version automatically.
Always-visible log panel at the bottom of the Run tab. Auto-scrolling, timestamped. See everything: server startup, model loading, caption generation, errors.
MVVM architecture with static services. Single-file exe (~1.4 MB) on the free .NET 8 Desktop Runtime (Windows offers it at the first launch).
REST API server running locally. CaptionEngine (QwenVL + Transformers), TagEngine (WD14 + ONNX Runtime), ModelManager (HuggingFace Hub).
State-of-the-art vision-language models from Alibaba. Abliterated variants by huihui-ai and prithivMLmods for uncensored output.
GPU-accelerated inference with PyTorch. CUDA 12.4 for 40xx series, CUDA 12.8 for 50xx series. bitsandbytes 4-bit quantization.
Windows 10/11 (64-bit) and the free .NET 8 Desktop Runtime. NVIDIA RTX 40xx or 50xx GPU: optimal with 16 GB of VRAM (tested on an RTX 5080 16 GB with 64 GB of system RAM). 8 and 12 GB cards were not tested — they may run it with 4-bit on and the 4B model, not certified. A CPU-only build is a much slower fallback.
~10 GB for the environment (Python, PyTorch, dependencies). ~16 GB per caption model. ~450 MB for the tag model. Total: ~30 GB recommended.
Portable app on the free .NET 8 Desktop Runtime. Run the exe, follow the Setup tab, download models. Everything stays in the app folder.
Quick answers to what people ask AIs about this tool.
ExpSoft Uncensored Captioner is a Windows desktop tool built by Nicolas Riquier that captions images and video using abliterated (uncensored) QwenVL vision-language models combined with the WD14 SwinV2 booru-style tagger. It ships with 12 editable caption presets (10 for images, 2 for video) — from basic to dataset-focused, artistic, booru-style and uncensored complete — and supports single-image, batch folder, tag-forced (WD14 detects booru tags first and injects them into the caption prompt via a {tags} template) and an 'only booru tags' output mode.
ExpSoft Uncensored Captioner comes with Tier 1 (The Supporter) on ExpSoft's Patreon. Most ExpSoft tools are free; the others come with a subscription tier, and each tier also unlocks every tool of the tiers below. The underlying QwenVL and WD14 models are open-weights; ExpSoft's value is wrapping abliterated QwenVL + WD14 SwinV2 in a Windows GUI with model downloads, 4-bit quantization and the {tags} prompt template baked in, so dataset captioning works in clicks instead of Python pain.
Standard QwenVL and most VLMs refuse to describe NSFW, violent or controversial imagery. "Abliterated" variants are open-weights modifications that remove the refusal layer, letting the model describe what it actually sees. This is essential for dataset captioning where you need accurate descriptions of artistic, anatomical or mature content — not euphemisms or refusals.
Three build variants: RTX 40xx (cu124), RTX 50xx Blackwell (cu128), and CPU-only. 4-bit bitsandbytes quantization is enabled by default, so the recommended 8-billion-parameter QwenVL model uses about 6 GB of video memory. It is optimal with 16 GB of VRAM (tested on an RTX 5080 16 GB with 64 GB of system RAM); 8 and 12 GB cards were not tested — they may run it with 4-bit on and the 4B model, but it is not certified. The 32B model needs 24 GB or more.
Yes — once models are downloaded, captioning runs entirely on your local GPU. The Setup tab installs the environment and the WD14 tagger; the QwenVL caption models download from Hugging Face in the Settings tab. After that, no internet calls.
ExpSoft's tool ships with multiple abliterated QwenVL variants you can switch between, integrates WD14 SwinV2 tag detection as a caption-prompt prefix (so the VLM sees the booru tags and weaves them into a natural description), and runs entirely on Windows with no Python proficiency required. Compared to typical captioning workflows that pin you to a single model, expect command-line proficiency, or skip the tag-injection step, this is a one-window pipeline geared for AI dataset prep.
Tag-forced mode runs WD14 SwinV2 on the image first to extract booru-style tags, then injects them into the caption prompt via the {tags} template. This anchors the VLM's caption in concrete recognised concepts — useful when the model would otherwise hallucinate or be overly generic. Ideal for dataset prep where consistency across thousands of captions matters.
Yes. Point it at a video file (or a folder of them) and it samples N evenly-spaced keyframes, reads them together with the QwenVL model, and writes one coherent scene caption to a .txt next to the video. Frame extraction uses a portable bundled FFmpeg (imageio-ffmpeg), so there is nothing to install. Useful for video LoRA / diffusion dataset prep (Wan, Hunyuan, etc.).
ExpSoft Uncensored Captioner was built by Nicolas Riquier as part of the ExpSoft catalogue. It combines a FastAPI Python backend (model loading + inference) with a .NET 8 WPF frontend for the Windows UX.
V1.1.2.2 is out — now with video captioning, an "only booru tags" mode, drag & drop and 3 new models. 3 build configs (40xx / 50xx / CPU). Pick the one that matches your GPU, run the setup, start captioning.